Inside AI SystemsJul 238 min read
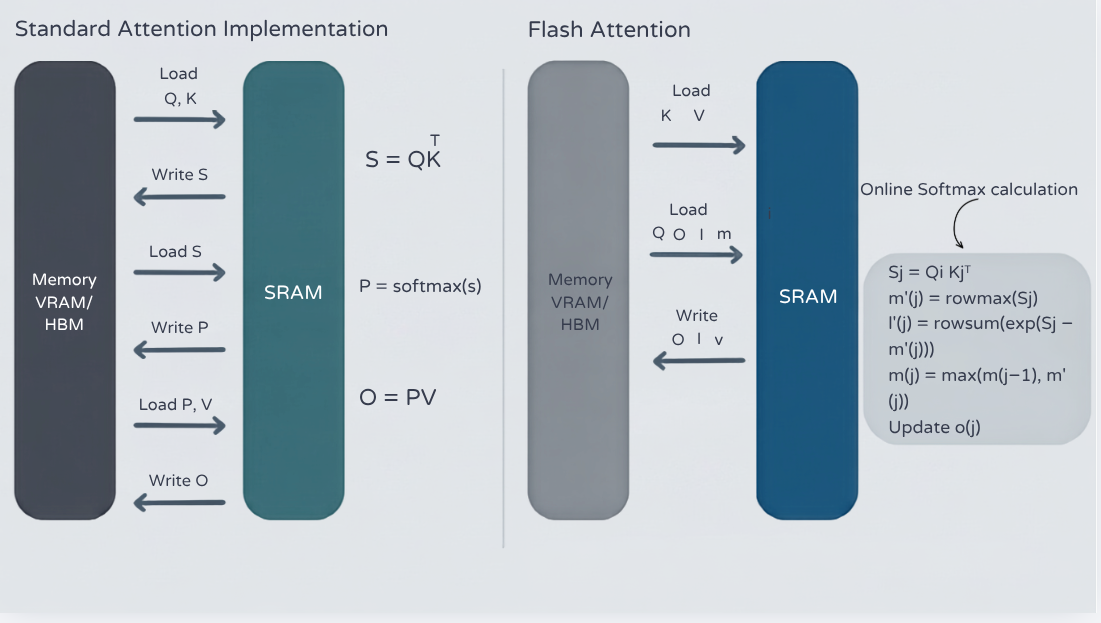
Multi-Head Attention To Flash Attention
What actually changes when you go from manual attention to a fused kernel
Quantization, pruning, distillation, speculative decoding, and serving large models cheaply.
2 articles
What actually changes when you go from manual attention to a fused kernel
Understanding Prefill and Decode in LLM Inference