
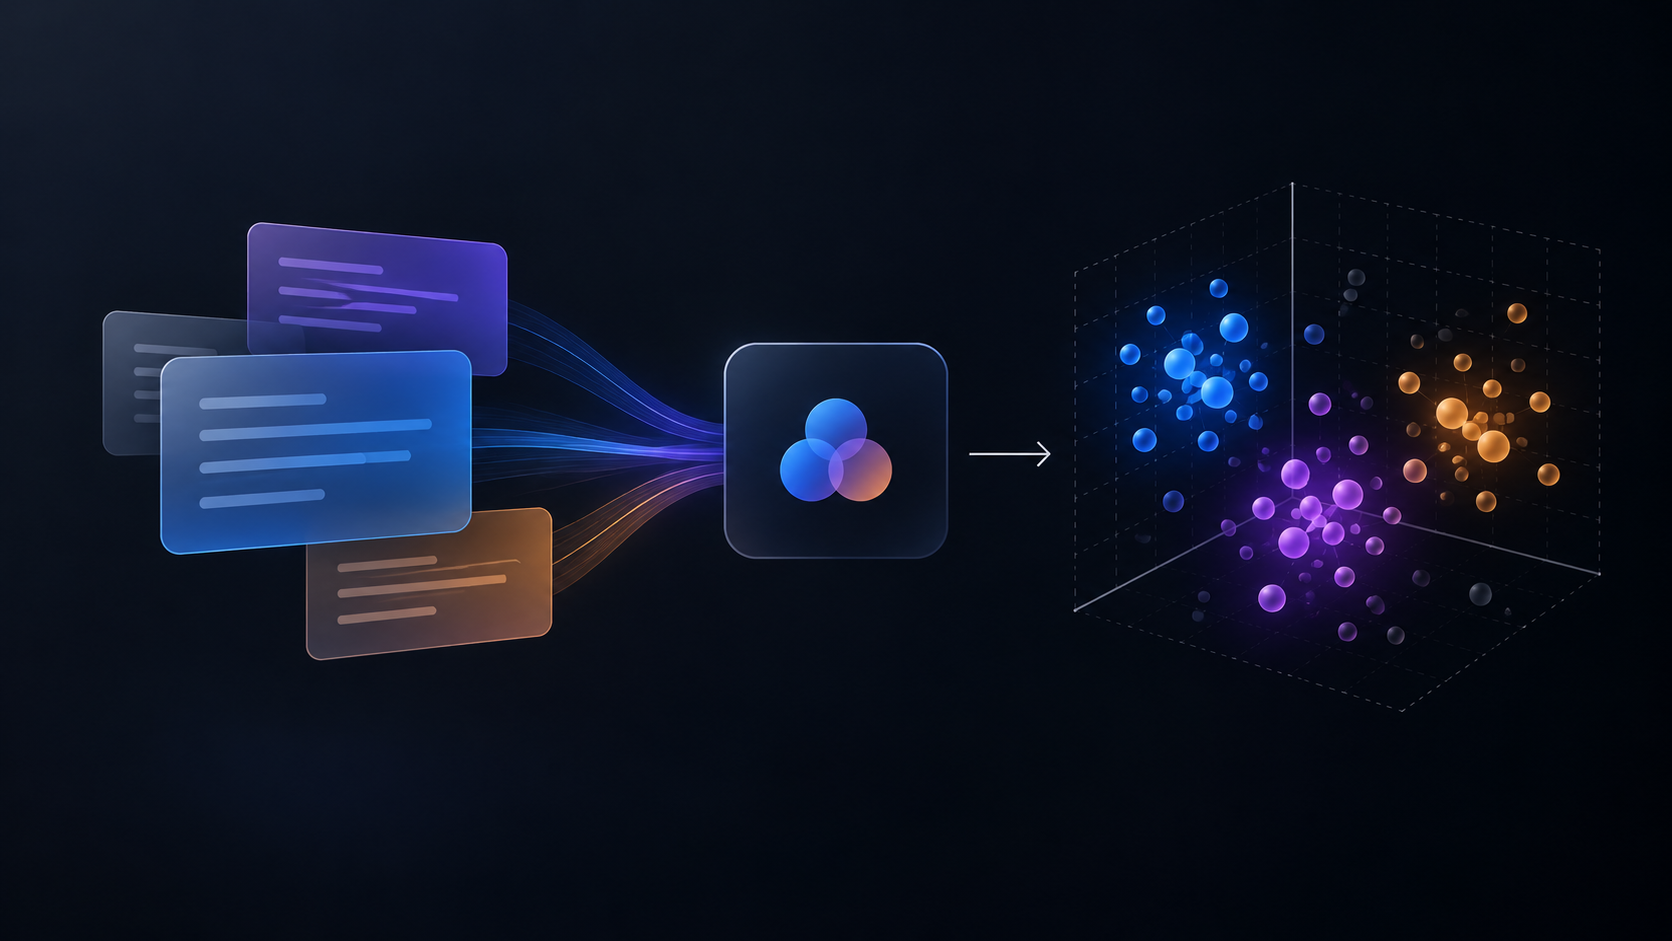
I want you to think about these two phrases:
I lost my job.
My employer fired me a week ago.
As we can see, both these phrases have no common words in them, yet they mean the same. This is because the context over here is the same. And that is something that we humans can understand. But how is it possible for AI to understand the meaning behind these phrases? The answer is embeddings.
If you are someone who is new to the field of AI engineering and want to understand how AI applications are built, understanding embeddings has to be your foundation. There are various applications in which embeddings act as the foundation.
So, without further ado let us dive deep into this topic and understand how it works.
Machines don't read words. They do not understand text. They understand numbers, but as we know, human language can be complicated. We might use the same words in two different sentences that mean different things.
For instance:
I have to withdraw money from the bank. Over here, bank is a financial institution.
My friend loves to catch fish near the river banks. Here, even though the word bank is the same, the sentence's meaning differs.
This is where embeddings help AI models to understand the context behind the sentence.
What is an embedding?
In simple terms, an embedding is a numerical representation of text, such as numerically representing a sentence, word, or paragraph. The idea is to take an input and convert it into a list of numbers known as a vector. For example, a vector, or a numerical representation of text, could be like [0.21, -0.1, 0.81, 0.5].
Now, you might read them as random numbers, but they are not. This is a meaningful representation that the model learns for every sentence, capturing useful patterns.
How do numbers represent meaning?
Think of these two sentences:
I love watching football.
Football is my favorite sport.
If you look closely, both sentences have a few different words, but they are very close in meaning. This is because we are talking about football.
Now let's compare the same sentences with a sentence like, "Tomorrow we have an algebra exam." That sentence is nowhere near the two sentences that we spoke about earlier.
An embedding model gives a numerical representation to all three of these sentences. But the vectors for the first two sentences would be much closer to each other than the third sentence because their meanings are similar. The topic is similar. We are talking about football over here. The other sentence would be closer to some other sentence where we are talking about a math exam.
The point that you need to understand over here is that an embedding learns a useful relationship between words and then gives a numerical vector to them.
How is this similarity calculated?
Once we have the two vectors, how exactly is the similarity calculated?
The most common technique that AI models use is known as cosine similarity.
The idea behind this technique is to compare the direction of two vectors. When their directions are similar, their similarity score is high. If they are opposite, their score is lower.
Usually, the score ranges from 0 to 1. And in some cases, it is -1 to 1.
If you see the two sentences that involve football, they might have a cosine similarity score of 0.77. When you take one of those sentences and compare it with the algebra exam, it might be 0.1.
A score closer to 0 means the vectors are opposite, which eventually means that there is no similarity between the sentences.
Why should AI engineers care about embeddings?
Embeddings power so many concepts that they form the foundation of AI engineering. For example, semantic search, retrieval-augmented generation (also known as RAG), and recommendation systems. All of these are powered by embeddings.
Embeddings are used in these techniques, so it becomes a no-brainer to learn embeddings.
The core idea is to turn text into numerical representations, and once you understand embeddings, concepts like semantic search or RAG become much easier.